Pittsburgh, Pennsylvania
Posts

Wait, Which PR Got Merged? What Five Closed PRs Taught Me About Open Source

September 27, 2026
Share
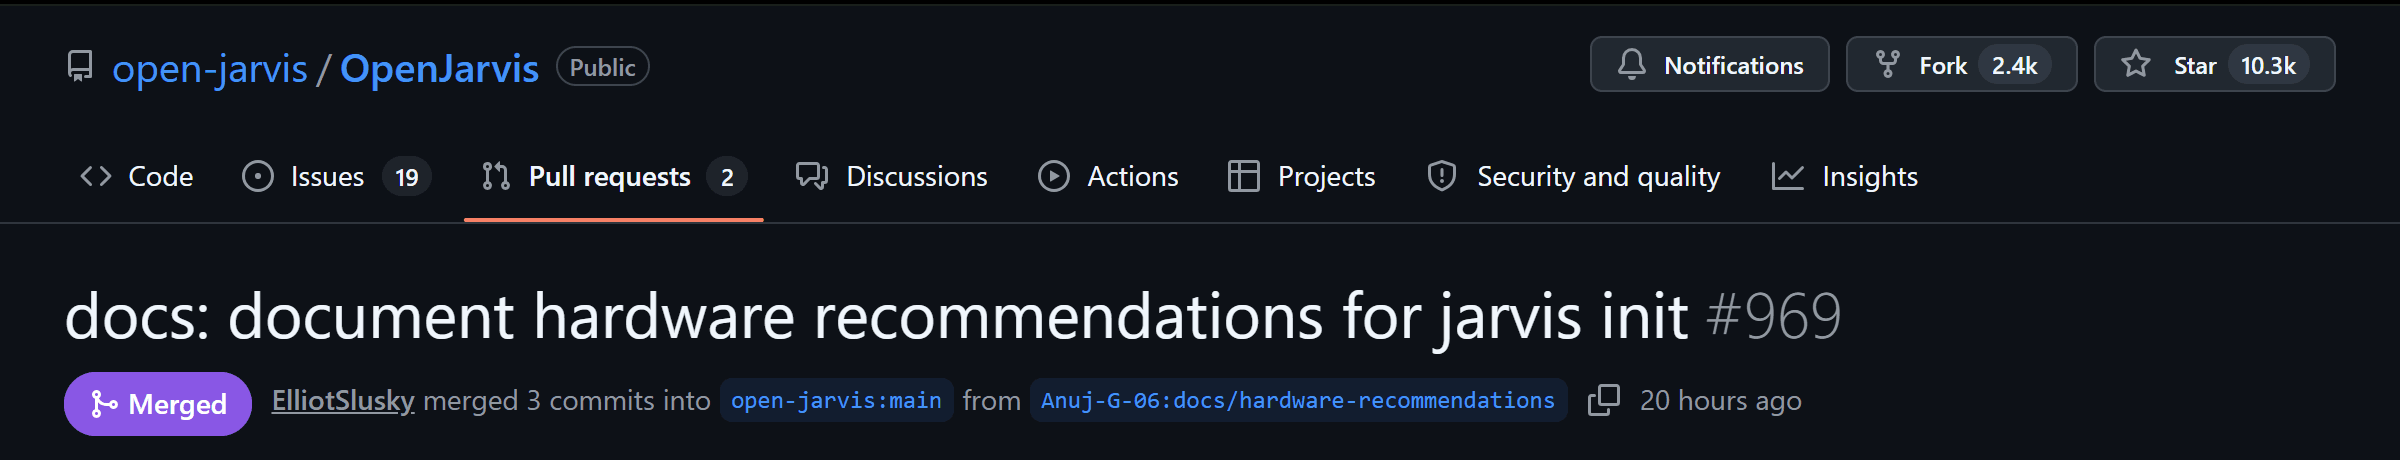
So on Saturday I'm deep in my CMU capstone, and a GitHub notification pops up: one of my PRs just got merged. My first thought, honestly, was wait, which PR? It was #969 in OpenJarvis, Stanford's "Personal AI, On Personal Devices" project. I read through the thread and realized I'd gotten a couple of things wrong in the docs. The maintainer had corrected them, left notes, approved it, and merged it anyway. I was ecstatic. It's a docs change, 101 lines, but it's the first time I've actually contributed something useful to a project I don't own. And it's in a space I genuinely love: small language models running on your own machine.
The merged pull request on GitHub: open-jarvis/OpenJarvis #969, "docs: document hardware recommendations for jarvis init", merged by ElliotSlusky into open-jarvis:main
I'm writing this because a lot of people want to contribute to open source and don't know where to start. I didn't either. If this saves even one person a few closed PRs, it was worth it. Early on I was basically padding my contribution count: quick drive-by PRs to big, famous repos. It wasted my time and the maintainers' time, and most of it wasn't even stuff I cared about.
The scoreboardThe open-source PRs I sent to other people's projects this year, and what each one taught me.
6PRs opened
1merged
19 daysfrom open to merged
  1. Feb 5
    Typo fixes and tokenizer testsWhat I learned: Search open PRs first. Someone had already fixed the typos.
  2. Mar 11
    A brand new pluginWhat I learned: Pitch a big feature in an issue before writing the code.
  3. Mar 21
    Docstrings and a SemanticF1 modeWhat I learned: One PR at a time. Three in two days is a lot to review.
  4. Sep 7
    Hardware docs for jarvis initWhat worked: Answer a question people are already asking.
Also, not every closed PR is your fault. Sometimes a repo isn't really maintained, reviews take months, maintainers are swamped, or you just don't know the codebase well enough yet. That's normal. Read more, and pick your spots. Here's what I didn't get at first. Contributing isn't a one-off, it's a habit you build. And it looks a lot like research, or honestly any good job:
How I contribute nowFive steps, the same loop as research. Under each one is how it went on OpenJarvis.
  1. ImmerseRead the code, the issues and the discussions before touching anything.On OpenJarvis: I read how jarvis init detects your hardware and picks a model.
  2. Understand the whyFigure out why things are the way they are. A lot of odd-looking code is a decision.On OpenJarvis: The recommendation logic was deliberate. It just wasn't written down anywhere.
  3. Spot the gapWhere the reasoning doesn't add up, or nobody wrote it down, that's a real limitation.On OpenJarvis: Users kept asking what hardware they need, in a discussion and then an issue.
  4. Formalize itWrite it down with evidence. If there's related work or literature, it helps your case.On OpenJarvis: I ran the code across RAM and VRAM sweeps and matched the project's own tests.
  5. Solve it their wayFit the fix to where the project is going. If the goal is A, build toward A.On OpenJarvis: One docs-only PR that closed the issue. No surprise refactors.
The step people skip is understanding the why. You can only spot a real limitation once you know why things are the way they are. If the reasoning holds up, it's not a bug, it's a decision. If it doesn't add up, now you've found something worth fixing. And the fix has to fit where the project is going. If the goal is A, you can't jump straight to Z. Sometimes you have to build the part in between first. The question was simple: what hardware do I need? The answer already lived inside jarvis init, it just wasn't written down. So I ran the recommendation code across every RAM size up to 120 GB and every VRAM size up to 90 GB, and wrote down what it picks:
What jarvis init picks for your machineThe bands I documented, generated by running the recommendation code rather than guessing.
2B
~1.1 GB
4B
~2.2 GB
9B
~5.0 GB
27B
~14.9 GB
GPU VRAM (one GPU)
1–8 GB9–17 GB18–35 GB36 GB+
System RAM (no GPU)
5–14 GB15–24 GB25–44 GB45 GB+
Dense Qwen3.5 models (qwen3.5:2b to qwen3.5:27b), approximate download sizes. My laptop is an RTX 5070 Ti with 11.9 GB of VRAM. AMD Radeon cards get their own default.
Two things in my draft were off. I called all four Qwen3.5 models mixture-of-experts, but two of them are dense. (The project's own catalog said the same thing, and that's getting fixed too.) And I treated the AMD path as a bug, when it's actually a deliberate exception with its own engine and default model. The maintainer, @ElliotSlusky, didn't bounce it back. They fixed both on my branch and merged it:
From open to merged19 days of waiting, then 52 minutes on Sep 26 from review to merge (Eastern time).
  1. Sep 7
    Opened
  2. 19 days
    Waiting
  3. 4:50 pm
    Two facts to fix
  4. 5:06 pm
    Fixed and approved
  5. 5:42 pm
    Merged
What I learned: check the adjectives, not just the numbers. And make everything else in your PR so easy to verify that fixing one wrong fact takes minutes.
  • Pick a project you actually care about.
  • Start from an open issue or discussion, not from an idea in your head.
  • Search open and closed PRs before you write a line.
  • Send one PR at a time.
  • Show your receipts: what you ran and what it printed.
  • Expect to be wrong about something, and make it easy to fix.
Contributing well is a skill you build one PR at a time. Mine took six.